INFRA FOR EMBODIED AI · LAY THE RAIL BETWEEN ACTION MODELS AND PHYSICAL ROBOTS
Open-RAIL: A Real-time Asynchronous Inference Linker for VLA/WAM Models and Robots
Asynchronous Inference · Motion Smoothing & Speed Scaling · Closed-Loop Evolution
Open‑RAIL is a plug‑and‑play open‑source asynchronous inference middleware for diverse VLA/WAM models and heterogeneous robots. Using two‑stage trajectory smoothing and fusing, it resolves inference‑control mismatch and motion jitter to boost execution speed, motion smoothness and task success rates while preserving original action policies. It supports runtime real‑robot data recording and human‑in‑the‑loop intervention for closed‑loop reinforcement learning.
Key Features
- Asynchronous Pipeline — decouples 5‑10 Hz VLA inference from 200‑500 Hz motor control, removes inference‑control waiting latency.
- Two‑stage Trajectory Smoothing — achieves near C² continuity and motion jitter drastically suppressed with acceleration std reduces ~100× ( 10+ → 0.1 rad/s²).
- Drop‑in Compatibility — supports 12 VLA/WAM models across 9 families & 3 heterogeneous robots in this release (Unitree G1 coming soon); new model adaptation needs only 50‑100 lines of code without retraining.
- Cloud‑Edge‑End Deployment — Server‑Client architecture supports robot‑local, edge and cloud execution over wired/Wi‑Fi/5G with respective latency of end‑side 3‑5 ms, edge 35‑45 ms, cloud 80‑120 ms, requiring zero upper‑level code modification.
- Enhanced Execution Throughput — achieves up to 2.09× speedup against raw policy output, outperforming tele‑operation speed with no need for recollecting training data.
- Universal Task Success Boost — lifts model success rate up to 0.95, with absolute gain Δ from +0.10 to +0.725 (evaluated on π₀.₅ and GR00T‑N1.5).
- Closed‑loop Evolution — auto LeRobot‑formatted real‑robot episode recording plus time‑aligned human‑in‑the‑loop tele‑correction to enable continuous iterative improvement.
China Mobile Embodied Intelligence Industry Innovation Center Presented by Embodied Model Team (TAO Team)
RAIL ARCHITECTURE
Open‑RAIL: The Infrastructure Bridging Diverse VLA/WAM Brains and Heterogeneous Robot Bodies
Open-RAIL Architecture Overview (click to enlarge)
RAIL Server
Task Scheduling · Model Inference
RAIL Client
Perception Collection · Realtime Data Manager · Motion Smoothing · Robot Execution · Human-in-the-loop Tele-operation
Web Panel
Execution Monitoring · Parameter Tuning · Camera & Trajectory Visualization · Evaluation & Data Recording · Robot Manual Control
OPEN-RAIL adopts a ZMQ-powered distributed pipeline: the RAIL Server performs task scheduling and VLA model inference to produce action chunks; the RAIL Client handles perception collection, time synchronization, trajectory smoothing and robot execution with human-in-the-loop tele-operation; the Web Panel supports runtime monitoring, parameter tuning, visualization, data recording, evaluation and manual robot control. Additional modules enable tactile sensing and cloud-edge collaborative closed-loop embodied AI operation.
CORE CAPABILITIES
Operable | Stable | Compatible | Evolvable
Capability 1
Operable
Zero-code operation — Monitor runtime status, tune parameters / instructions, and visualize trajectories / cameras through an user-friendly Web Panel.
Open-RAIL ships with a browser-based Web Panel that turns the pipeline into something anyone can operate without writing code — live stats and camera streams, 40+ runtime parameters tunable on the fly, and one-click run control, all from a single console.
▸ Expand technical details ▾ Collapse technical details
- •Live monitoring: WebSocket pushes runtime stats every 250 ms — FPS, latencies, buffer occupancy, CPU / GPU / memory, bandwidth, and ZMQ connection state.
- •Live visual: camera and scene video streamed over the visual WebSocket (port 8765) for real-time situational awareness.
- •Config & instruction tuning: hot-patch YAML config (40+ runtime parameters) and natural-language task instructions at runtime — no restart required.
- •Independent run control: observe, infer, and control threads can be started and stopped independently — e.g. pause inference while keeping observation live, or stop control without dropping the data stream.
- •Manual robot control: take over via teleoperation to directly drive the robot and correct actions in real time when the model misbehaves.
- •Episode review: browse, replay, and delete LeRobot-format episode and evaluation records for offline analysis and further training.
Capability 2
Stable
Asynchronous inference pipeline + Intra-Chunk Smoother & Inter-Chunk Fuser
A three-thread asynchronous pipeline (observation 30 Hz, inference 5-10 Hz, control frequency 200–1K Hz) decouples robot execution from VLA model inference. The control thread reads pre-filled action buffers, reducing idle-wait latency from full inference time to near-zero. Two-stage trajectory post-processing composed of Intra-Chunk Smoother and Inter-Chunk Fuser suppresses in-chunk jitter and cross-chunk discontinuities, dropping joint acceleration std-dev from 10+ down to 0.1 rad/s², meanwhile achieving up to 2.09× task-execution speedup versus raw VLA baseline.
▸ Expand technical details ▾ Collapse technical details
- •Asynchronous pipeline: Three independent threads (observation / inference / control) communicate via queues. The control thread runs at configurable 200–1K Hz and consumes pre-filled action buffers and never blocks for model inference. Idle waiting latency is decoupled from inference latency (near zero), absorbing the large frequency gap between low-rate VLA inference and high-frequency robot motor control.
- •Intra-Chunk Smoother — eliminates jitter inside individual action chunks. Supported modes: raw baseline, CubicSpline interpolation for joint trajectories + zero-order-hold for grippers, least-squares polynomial fitting (configurable polynomial degree, default 4). Polynomial fitting derives velocity and acceleration from trajectory derivatives; gripper commands adopt local threshold filtering. Output yields continuously-differentiable trajectories to suppress intra-chunk oscillation.
- •Inter-Chunk Fuser — eliminates abrupt jumps between successive action chunks. Supported modes: search-action motion resync, PD-tracking smooth-velocity with velocity-acceleration clamping, default quintic min-jerk blending with adaptive segment length, direct sync pass-through. It enforces smooth state transition across chunk boundaries and avoids discontinuity spikes.
- •Overall effect: Joint acceleration standard deviation drops two orders of magnitude (10+ → 0.1 rad/s²), mitigating mechanical shock to robot hardware. The framework enables faster-than-teleoperation task execution with up to 2.09× speedup compared against unprocessed raw VLA outputs.
Capability 3
Compatible
Switch models, robots, or deployments without rewriting upper logic
RobotBase unified hardware interface, standardized inference interface, and Server-Client distributed architecture collapse robot swaps, VLA-model swaps, and deployment swaps into low-level configuration.
▸ Expand technical details ▾ Collapse technical details
- •Switch robots: RobotBase unified hardware interface, action_layout unified action mapping; AgiBot G1, China Mobile Lingxi and NAVIAI-WA2 ship in this release, with Unitree G1 coming soon.
- •Switch VLA models: standardized input/output inference interface; already supports 12 models across 9 families — GR00T N1 / N1.5 / N1.6, π0, π0.5, TAO, GO1, SmolVLA, ACT, RDT, DM0.5, WALL-X; integrating a new model needs only 50–100 lines of business code.
- •Switch deployments: Server-Client end-edge-cloud distributed architecture; Server can run on local body / edge / cloud, Client on the robot; switch deployment by changing only the comms address with zero upper-logic changes and auto-reconnect heartbeat.
Capability 4
Evolve
Running is data, intervention is teaching — the train-collect-evaluate flywheel
Automatic real-robot recording, online scoring, and human teleop correction form the train-collect-evaluate loop: inference execution → runtime collection → task evaluation → model retraining.
▸ Expand technical details ▾ Collapse technical details
- •Collect by running: real-robot runs auto-record images, joints, model outputs, and control commands into standard Parquet Episode data with incremental appends.
- •Evaluate by executing: sub_task online scoring written synchronously, exportable as JSON / CSV and linked to the Episode.
- •Teach by intervention: VR teleop human-correction hybrid mode; when the model errs, a human intervenes and the human trajectory is time-aligned with the original inference trajectory to produce high-quality training samples.
- •Train-collect-evaluate flywheel: inference execution → runtime data collection → task evaluation feedback → model retraining; one pipeline pushes models to the robot and returns real-robot data back for training.
PLUG-AND-PLAY COMPATIBILITY
Drop-in compatibility with mainstream VLA/WAM models and robots
Swap a model, a robot body, or a deployment target without rewriting upper-layer logic — Open-RAIL adapts through low-level configuration.
Supported VLA/WAM Models
12 supported · 8 release soonWe define the Unified Model Interface (UMI), a standard interface for model inference that specifies input/output data formats and preprocessing methods. It currently supports major open-source VLA models, and we welcome community contributions to integrate additional models.
GR00T N1
NVIDIA GR00T humanoid foundation
GR00T N1.5
NVIDIA GR00T humanoid foundation
GR00T N1.6
NVIDIA GR00T humanoid foundation
π0
Physical Intelligence VLA
π0.5
Physical Intelligence VLA
TAO(ours)
China Mobile TAO Team VLA base model
GO1
AgiBot GO-1 generalist VLA policy
SmolVLA
HuggingFace SmolVLA VLA policy
ACT
Action Chunking Transformer
RDT
Robotics Diffusion Transformer
DM0.5
OpenDM diffusion policy
Wall-OSS-0.5
Wall-X policy
T-Rex
Release soonVisual-prompt VLA
DeCAL
Release soonDeCAL adaptation
DreamZero
Release soonZero-shot visuomotor policy
GigaWorld-Policy-0.5
Release soonGigaWorld world-model policy
LingBot-VA
Release soonLingBot VLA model
GR00T N1.7
Release soonNVIDIA GR00T humanoid foundation
GR00T N1.7 EEF
Release soonGR00T N1.7 end-effector variant
XVLA EEF
Release soonXVLA end-effector variant
Supported Robots
3 in this release · 1 coming soon · 1 simulation backendWe define the Unified Robot Interface (URI), a standard hardware interface that unifies robot control commands and state feedback. It supports heterogeneous robot bodies plus a simulation backend, and we welcome community contributions to integrate more robot hardware.
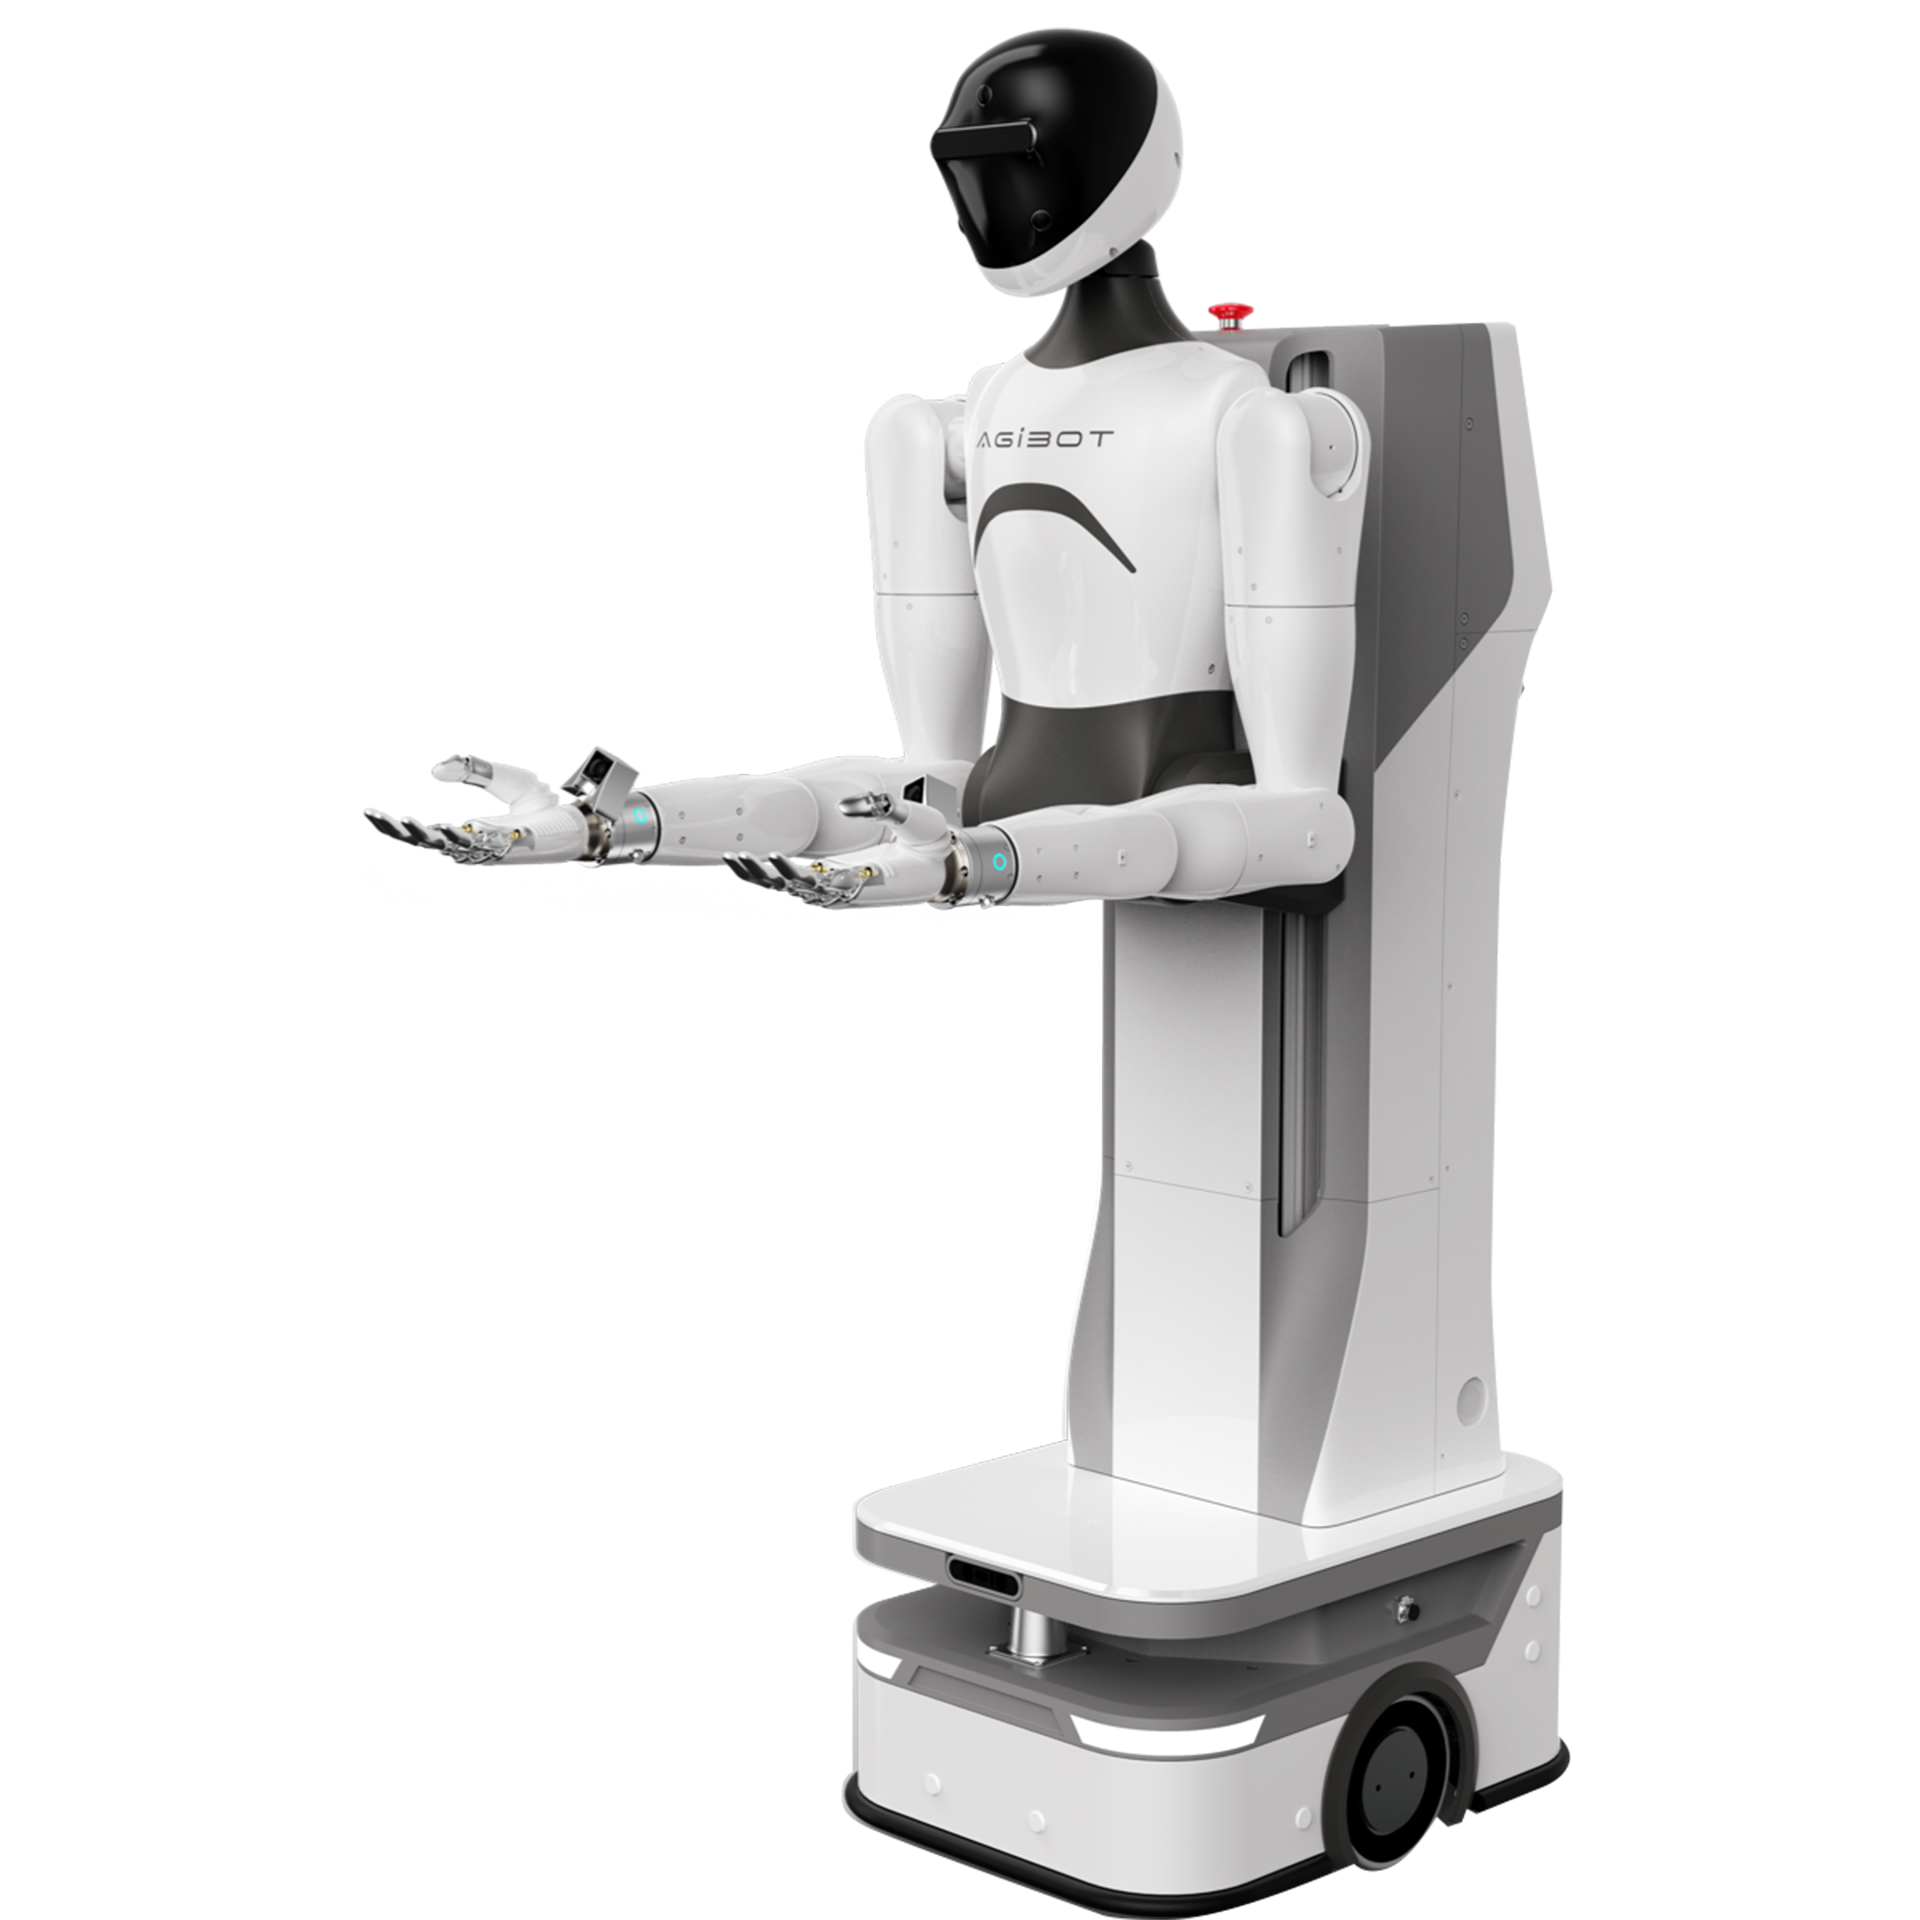
AgiBot G1
Dual-arm wheeled humanoid
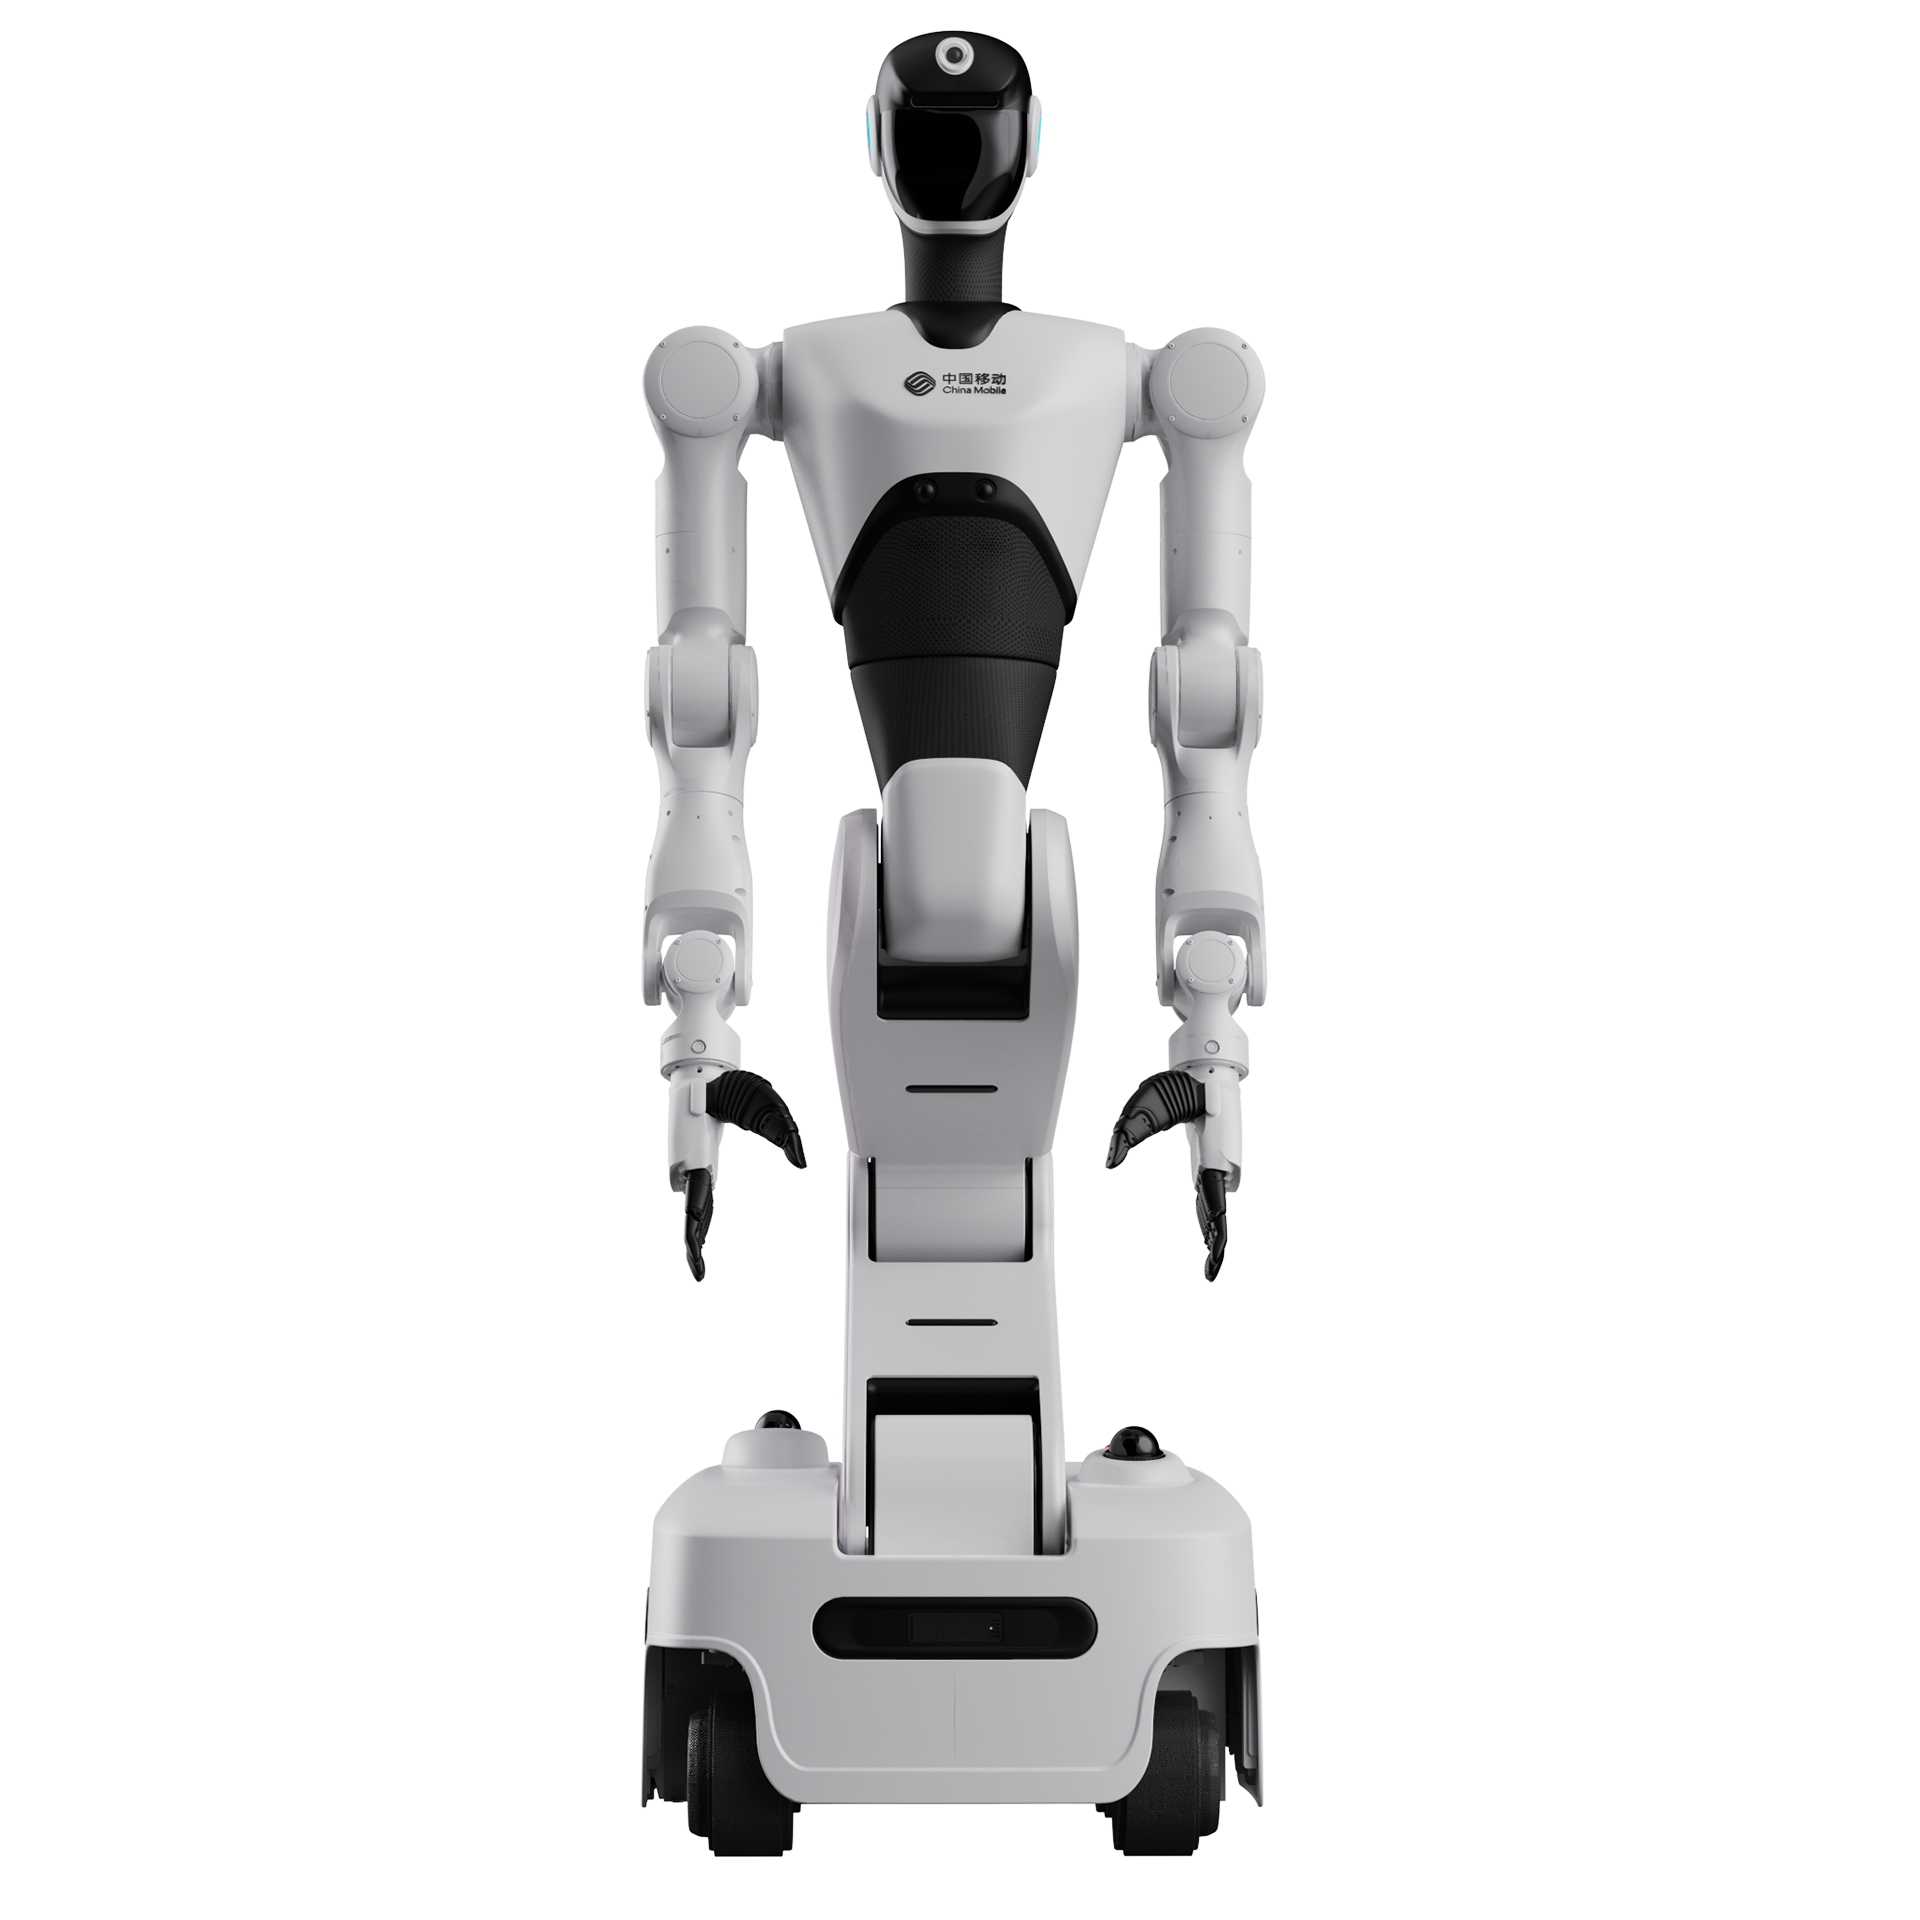
China Mobile Lingxi
Folding wheeled dual-arm humanoid
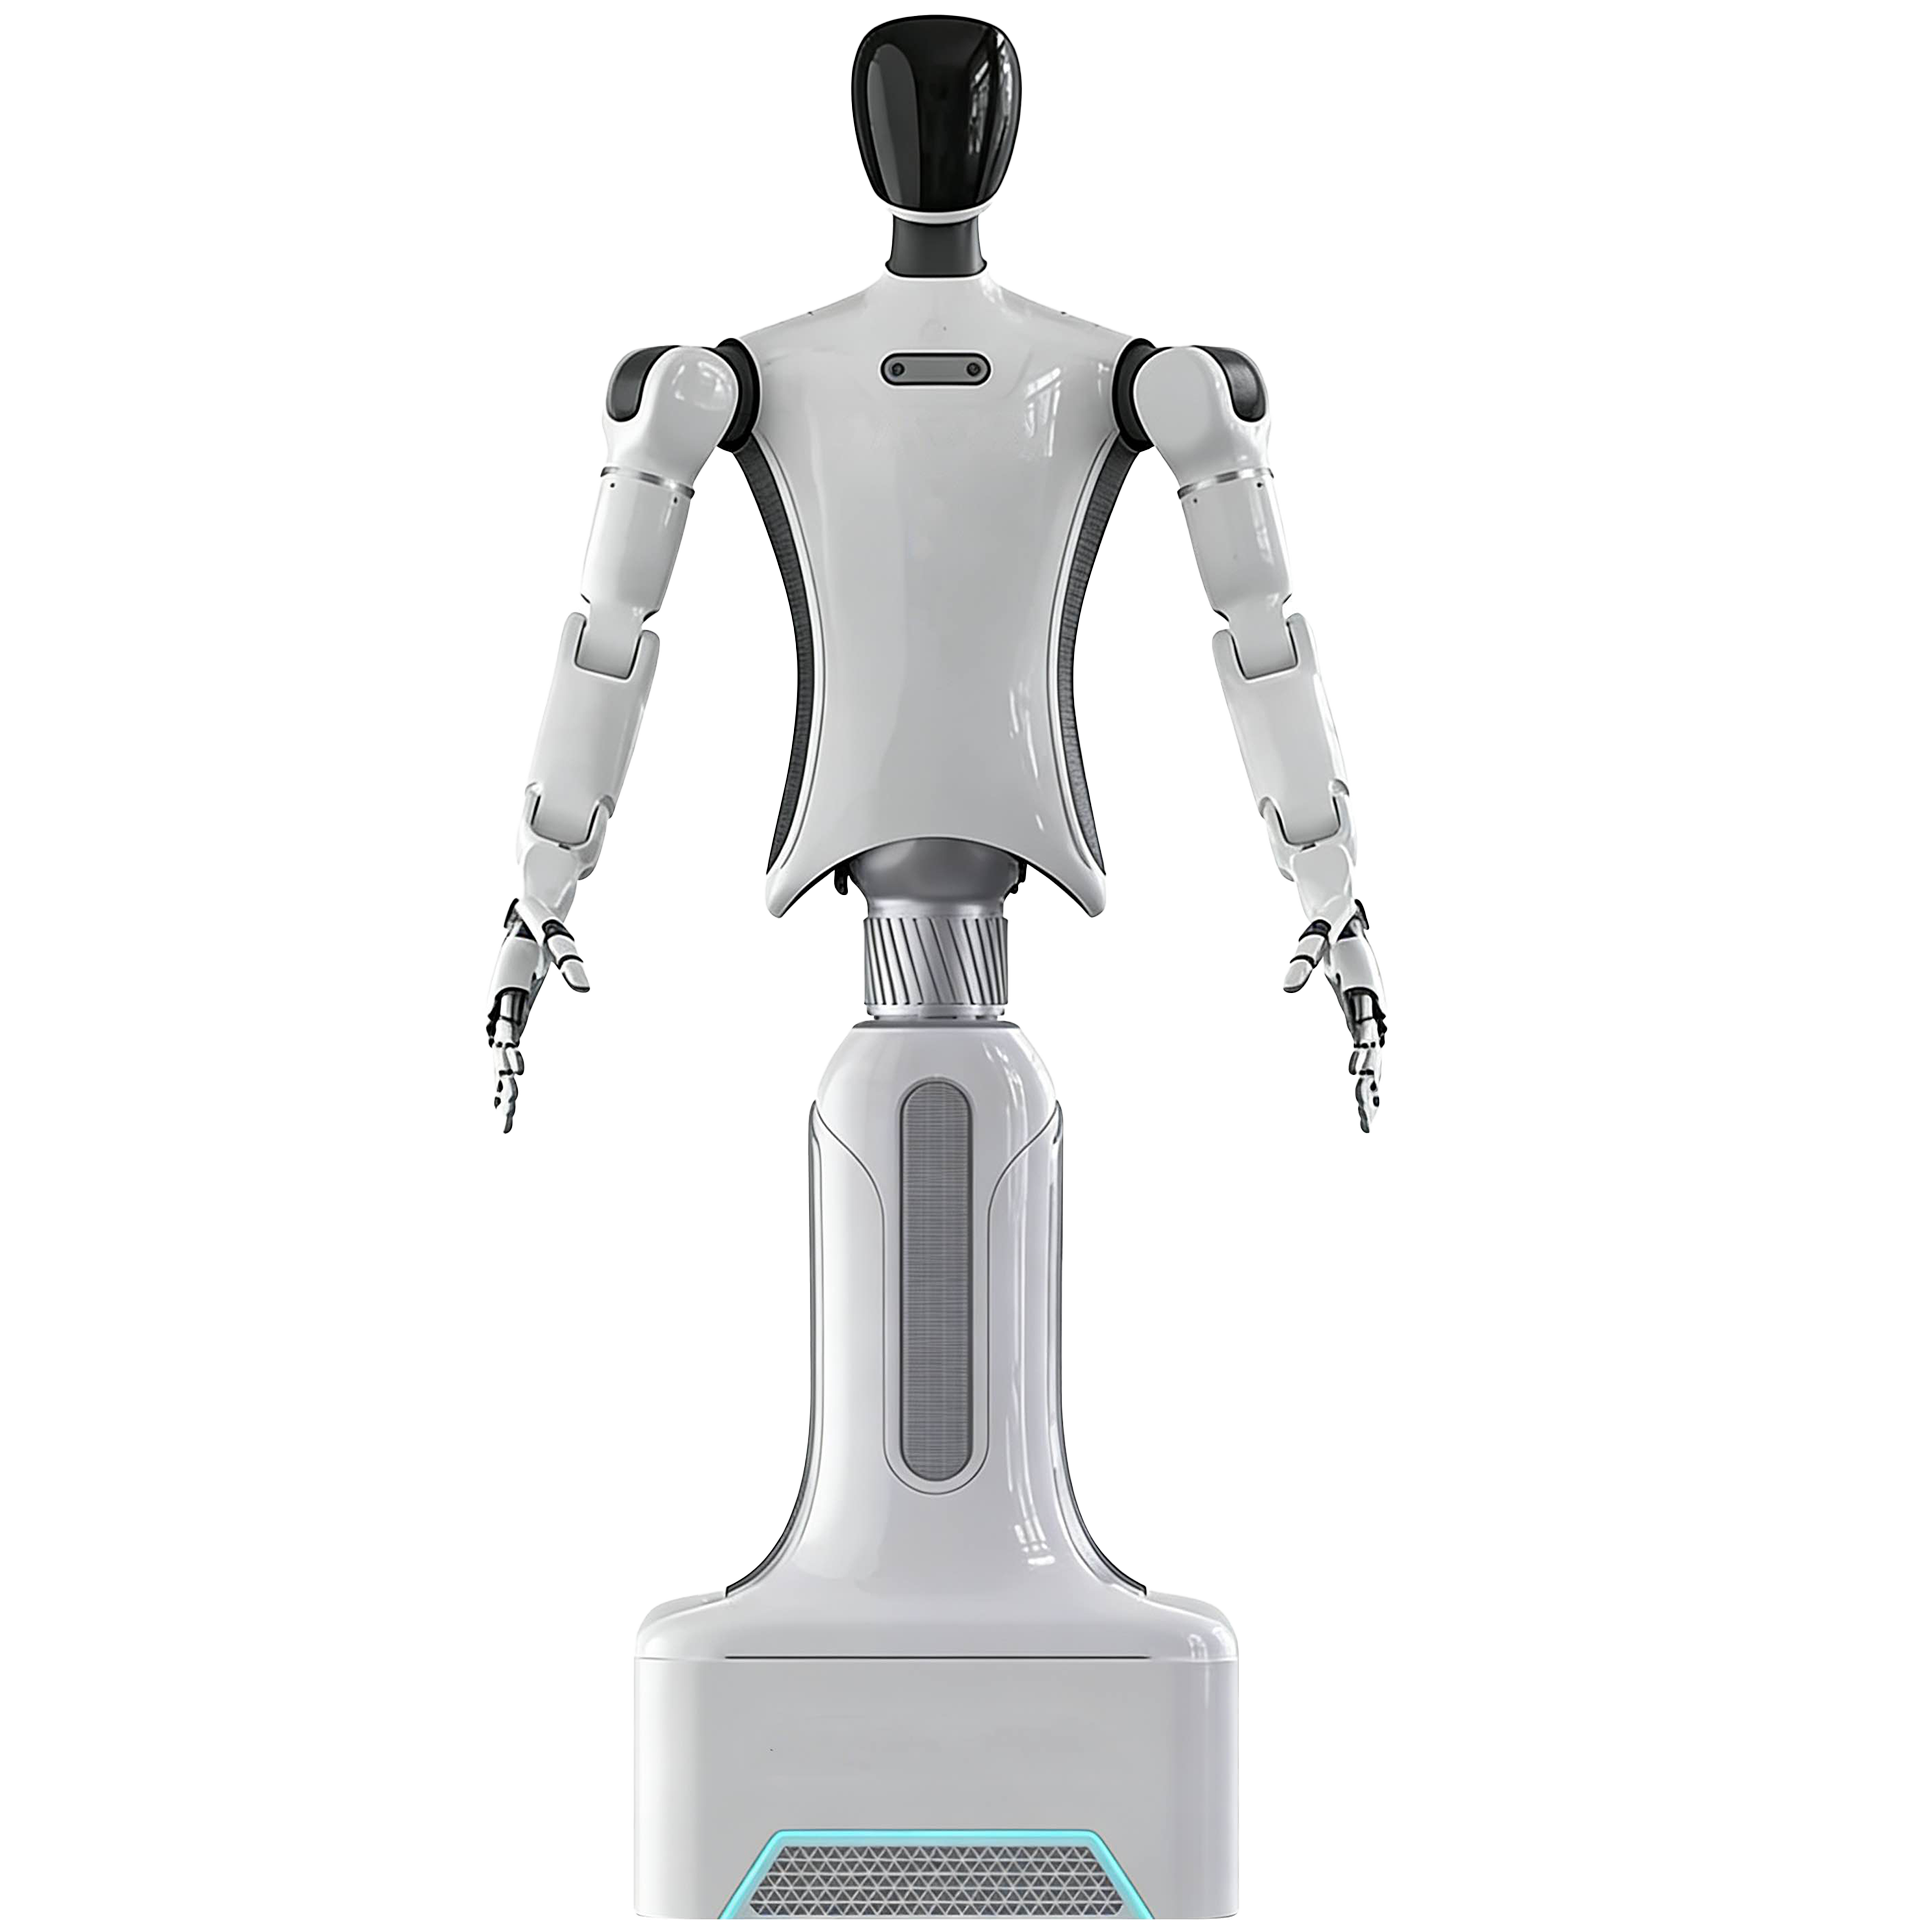
NAVIAI-WA2
Dual-arm wheeled humanoid
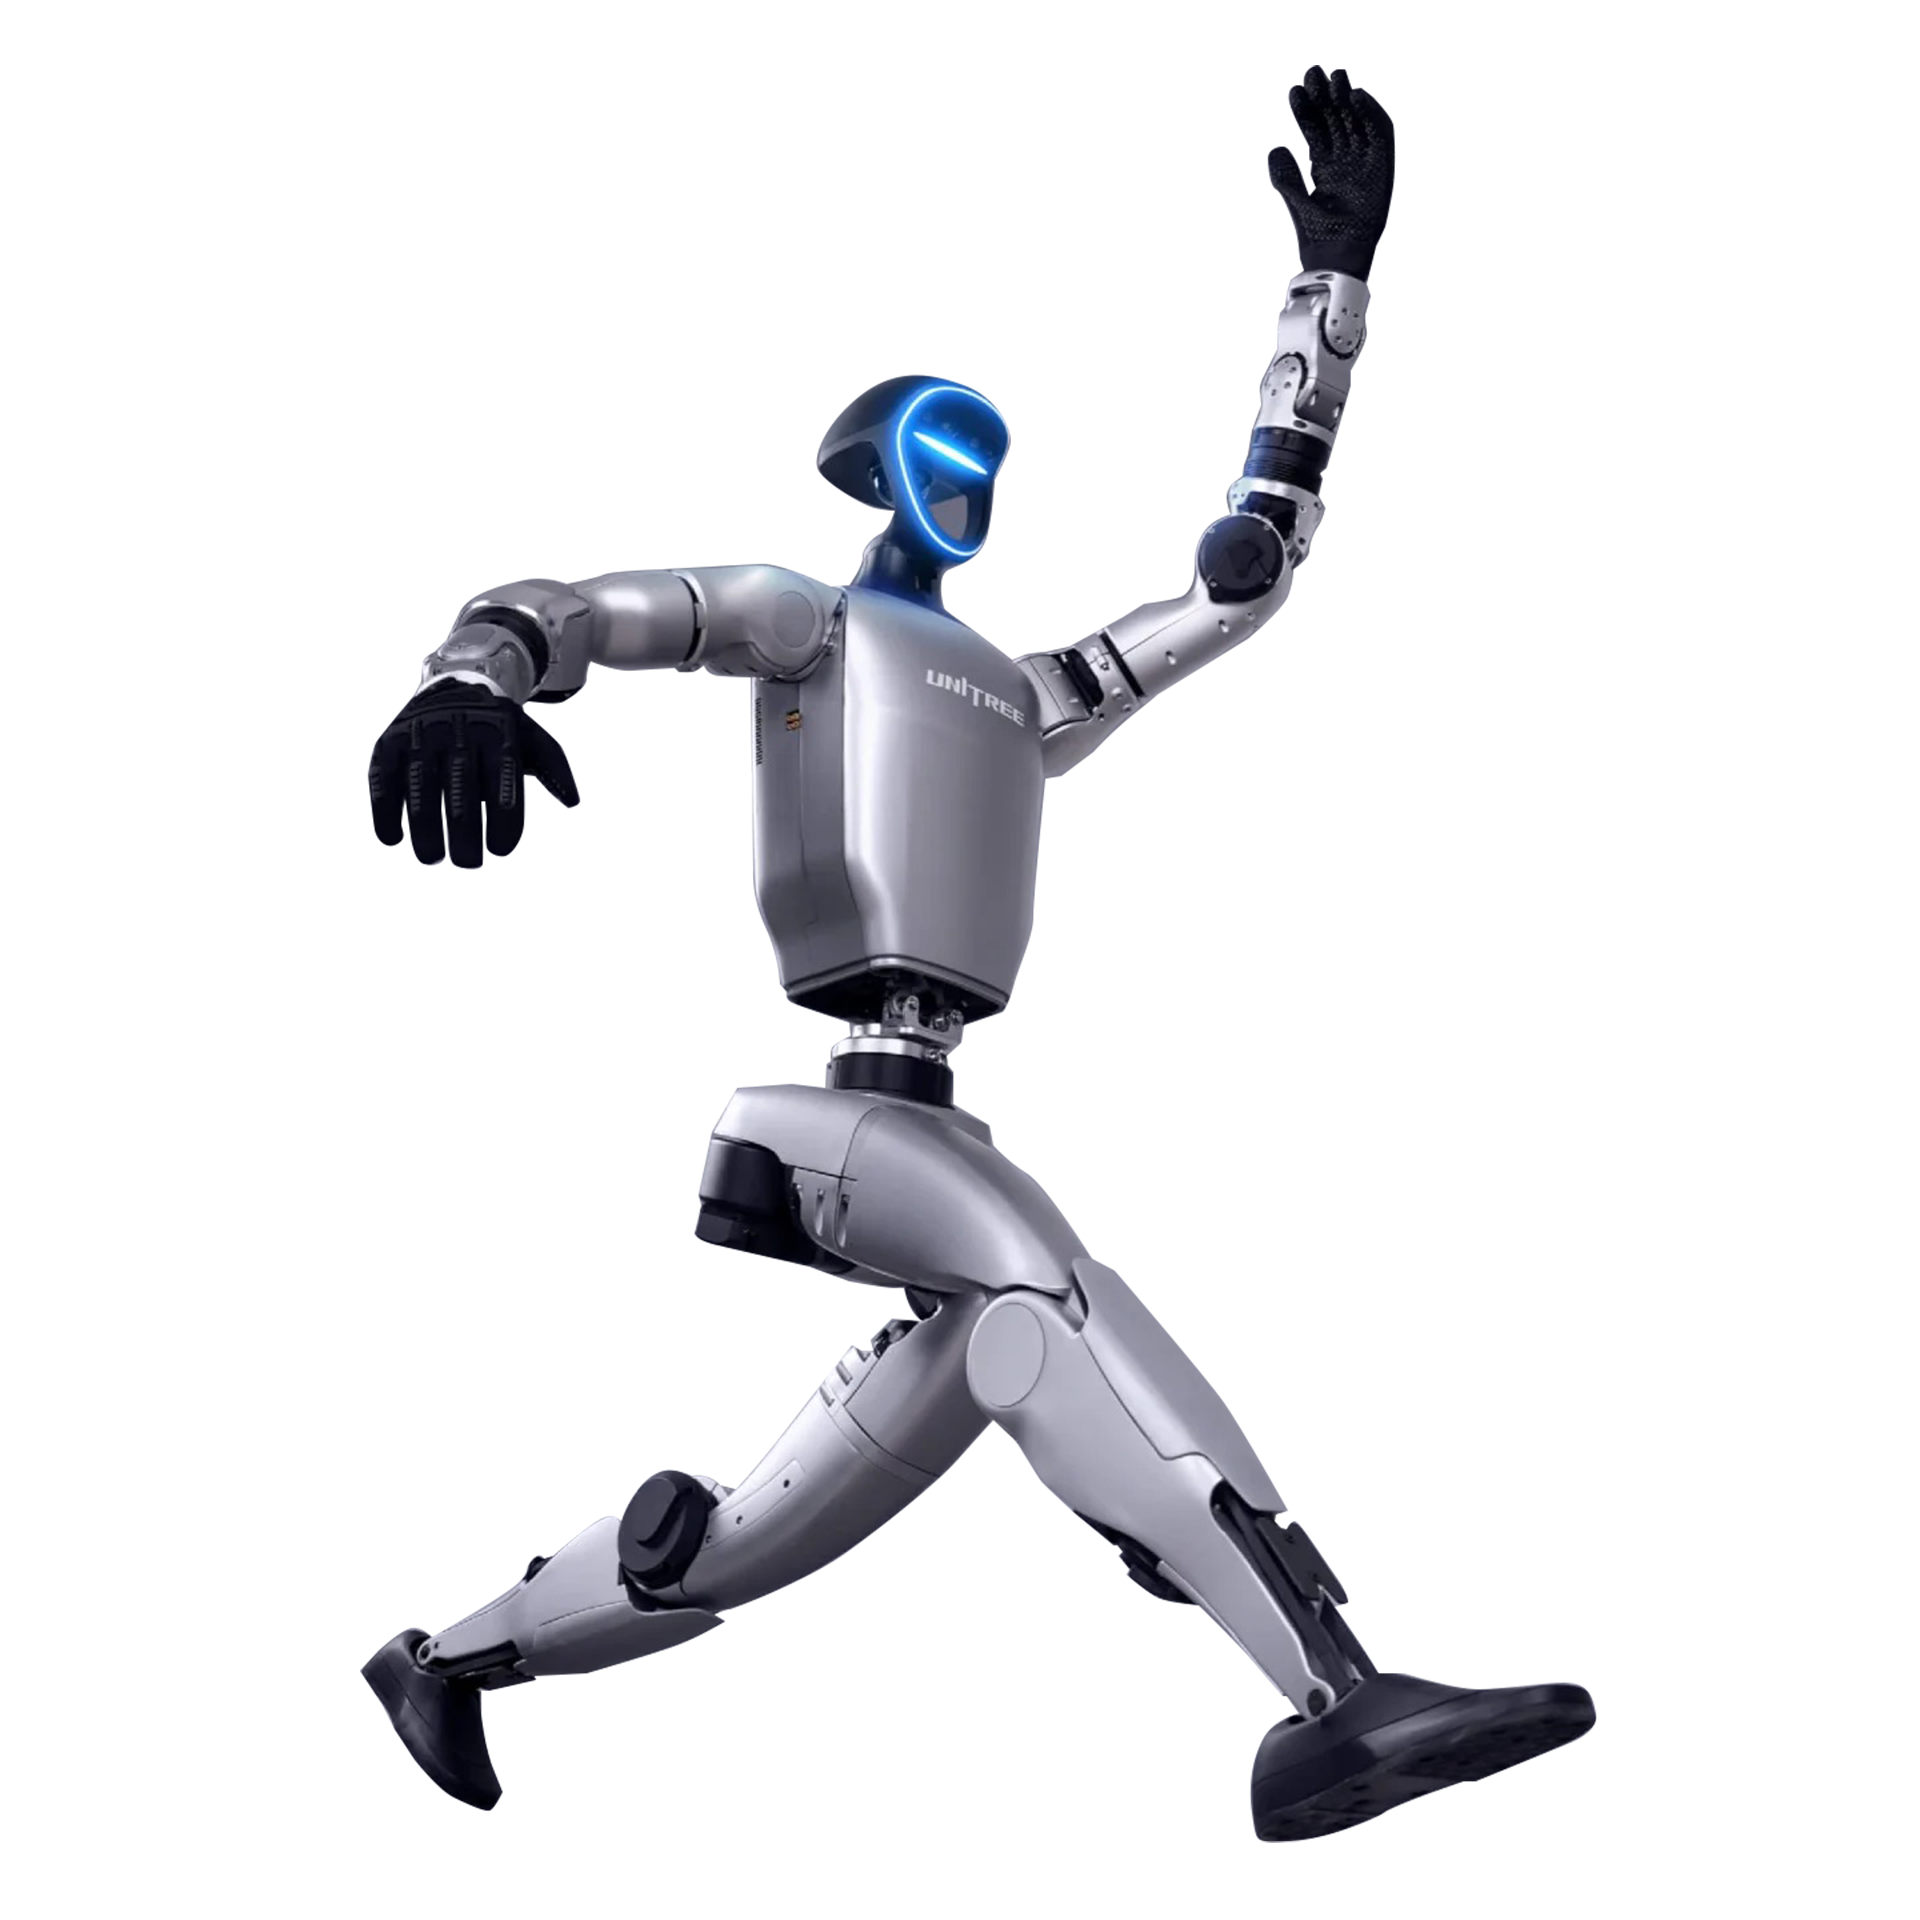
Unitree G1
Dual-arm bipedal humanoid
Coming soonMock
LeRobot simulation backend, no hardware needed
SimulationOPEN COMMUNITY
Build it once. Run it everywhere.
Everything here is ready to use, and what comes next is still unwritten — bring your model, your robot, your patch, or just what you learned. Questions and pull requests are welcome.
Who it's for
Pick the one that sounds like you.
Robot manufacturers
Ship one integration, and every model we have adapted runs on your robot — 20 models, plus every model the community adds later. You integrate once, not once per model.
Model developers
Integrate once, and your model runs on every robot we have adapted — 4 heterogeneous robots, with no robot-specific code. Each one means one more team that can run your model and reproduce your results.
Research institutions
Swap the model, the robot or the config — collection, evaluation and recording stay on the same path, so every combination is measured the same way, in the same data format. A comparison is one config change away, not another integration.
Solution integrators
A scenario you tune once is a scenario you can deploy again — next site, next customer, same config. On-device, edge, or cloud: same code, one endpoint to change.
Ways to contribute
Integrations
Bring your robot or model
Robots use URI, models use UMI — both already defined, and everything on the compatibility list is wired through one of them: 20 models and 4 robots. One integration — your model on every robot, every model on your robot. Model side needs no hardware: develop against recorded data.
Shared runtime
Improve the shared core
Smoothing, evaluation, data recording and transport sit in the shared runtime — the same path every model and every robot runs on. Change one module here, and every model–robot pair gets it.
Tooling & docs
Share what you learned
The docs, the Web Panel, visualization, config — all open, all ready to use today. A better config, a pitfall you hit, a tip worth passing on: that is a contribution, and most first PRs land here. Not sure where to start? Come talk to us first — asking counts too.
GET STARTED
Three-Step Workflow: Run VLA/WAM Models for Robot Manipulation Using Open‑RAIL
Set Up
-
Prepare the Environment
Install the required dependencies and set up the Open-RAIL runtime environment.
-
Start the Model Server
Select the VLA/WAM model and checkpoint, then launch the inference server.
-
Launch the Web Client
Start the Web Client and open the Open-RAIL interface in your browser.
Connect
-
Load the Robot Configuration
Select the target robot and load its corresponding configuration.
-
Review and Apply Settings
Check camera inputs, robot states, action mappings, control parameters, and communication settings, then apply the configuration.
-
Verify Robot Observation
Start observation and confirm that camera feeds and robot states are received correctly.
Run & Iterate
-
Set the Task
Select the task and language instruction for the current execution.
-
Run Inference and Control
Start inference, check the model outputs and processed action trajectories, then enable control to execute the processed actions on the robot.
-
Monitor, Intervene and Record
Monitor camera feeds, action trajectories, robot states, and runtime metrics. Pause and intervene through teleoperation when needed, while recording execution and correction trajectories for evaluation and further training.
Documentation
Developer resources: hands-on video library | full technical docs | developer community
Tutorials Video
Hands-on tutorial for Open-RAIL
All tutorial videos are narrated in Chinese. Please feel free to contact us if you need assistance and do not understand Chinese.